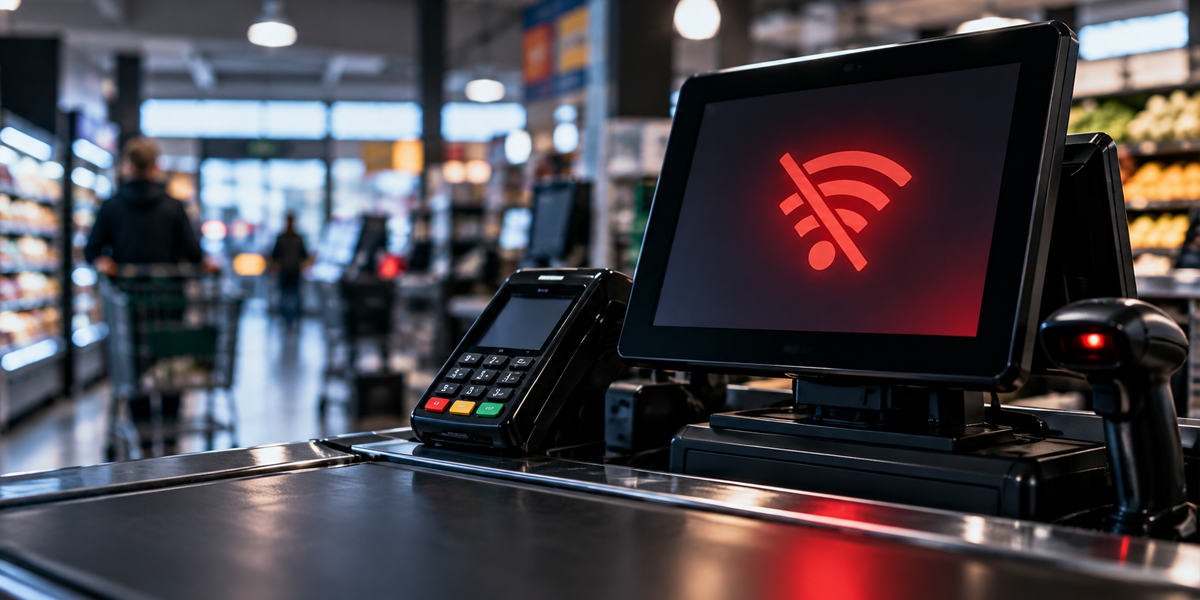
When Backup Connectivity Fails, the Store Doesn’t “Degrade,” It Stops
Store leaders and IT teams know the script: primary circuit goes down, traffic fails over, the store keeps running. On paper, it looks like resilience. Backup connectivity in multi-site retail and grocery environments often fails in subtler, more damaging ways. Not always as a dramatic outage, but as partial failures that break payment flows, interrupt fulfillment, degrade guest experience, and force frontline staff into manual workarounds that do not scale.
Connectivity is now the operating system of the modern store. It powers point of sale, loyalty, digital coupons, inventory accuracy, self-checkout, e-commerce pickup, workforce tools, security, and the vendor ecosystem that keeps the building running. When the backup link does not perform, the store loses its ability to transact and execute.
This article breaks down what happens at the store level when failover fails, why traditional approaches are unreliable in practice, and what a managed failover strategy looks like for enterprises that cannot afford connectivity gaps.
The real definition of downtime in retail and grocery
Downtime is rarely a single binary event. In distributed environments, the most common and costly scenario is “brownout” behavior: enough connectivity to look alive, but not enough to keep critical applications stable. Many organizations underestimate risk because a backup circuit may show as “up.” However, the store experiences failed authorizations, delayed price updates, or broken integrations that stall operations.
Customer intent and labor efficiency are real-time in retail and grocery. The margin for error is thin. A short disruption during peak hours can ripple across the entire day, especially when teams are forced to switch to manual processes, store managers start calling the help desk, and transaction exceptions pile up.
What happens at the store when backup connectivity fails
When failover does not behave the way you expect, store operations do not fail gracefully. They fail in a cascade. Below is a realistic sequence many enterprise teams recognize.
- Payments become inconsistent. Card authorizations time out or fall back to offline modes. Some lanes work, others fail. Staff retry transactions, customers abandon carts, and exception reporting grows.
- POS and store systems drift out of sync. Price files, promotions, loyalty, and tax updates may not apply correctly, creating checkout friction and forcing overrides that slow throughput.
- Fulfillment slows or stops. Buy online, pick up in store, and curbside workflows depend on stable connectivity for order release, substitutions, and status updates. When the store cannot reach core systems reliably, fulfillment becomes manual and error prone.
- Inventory accuracy degrades. Scanning, cycle counts, receiving, and perpetual inventory updates lag, impacting replenishment and availability. This creates more issues as it compounds across locations.
- In-store experience breaks. Self-checkout, digital signage, kiosks, and guest Wi-Fi depend on network performance. While not “mission critical,” failures increase labor burden and degrade brand perception.
- Security posture weakens. If backup connectivity forces routing changes, segmentation policies may not apply the same way, or logs may stop flowing consistently. That risk multiplies during an incident.
- Frontline teams improvise. Managers make judgment calls on offline transactions, manual price overrides, or paper-based fulfillment steps. The organization absorbs risk because there is no consistent operational playbook for connectivity failure.
None of this is theoretical. It is what happens when the network is not engineered and managed as a business continuity system.
Why traditional failover strategies look good on paper and fail in practice
Many retail and grocery enterprises have a backup link, but the design and operational model assume that “a second circuit equals resilience.” However, this assumption breaks down for several reasons.
- Failover is not the same as recoverability. A router can detect a primary outage and switch paths, yet applications still fail due to latency, packet loss, jitter, or DNS behavior that was never validated under backup conditions.
- Backup links are often undersized. A store’s traffic profile has changed. Cloud POS, SaaS security, video, IoT, and digital experience tools consume bandwidth and require consistent performance. A backup circuit that was “fine” years ago may no longer support today’s workloads.
- Testing is infrequent or unrealistic. Many organizations test failover during off-hours or only validate link status, not application-level outcomes. The first real test becomes a real outage.
- Carrier diversity is assumed, not verified. Two circuits can still share upstream dependencies. If the same provider, same last mile, or same regional infrastructure fails, both paths can degrade together.
- Store edge complexity keeps growing. SD-WAN policies, LTE, broadband, firewall rules, and cloud security stacks create more configuration states. Without standardization and continuous monitoring, failover behavior varies store to store.
- Visibility stops at the circuit level. “The link is up” does not answer the right question. You should ask: can the store perform critical workflows, right now, under backup conditions?
The financial and operational consequences add up faster than most models predict
Retail and grocery leaders often try to translate downtime into a clean dollar figure. The real cost is broader and more persistent than a single lost-sales calculation.
- Lost transactions and abandoned baskets. Customers will not wait through multiple payment retries.
- Labor inefficiency. Manual processes and overrides create extra touches, training burden, and downstream reconciliation work.
- Fulfillment penalties. Missed pickup windows and inaccurate status updates erode customer trust and increase support volume.
- Inventory and pricing errors. When systems drift, you get shrink exposure, margin leakage, and poor availability.
- Brand damage. Inconsistent experiences, especially in grocery and essentials, drive customers to alternatives quickly.
- Security risk and compliance exposure. Loss of monitoring, log continuity, or segmentation consistency is not just an IT problem.
For distributed enterprises, the most dangerous scenario is not a single outage at a single store. It is recurring, partial failures across dozens of locations that consume operating margin and customer loyalty.
Resilience when it matters most requires managed failover, not just backup connectivity
Backup connectivity becomes a true continuity layer only when you design, validate, and operate it as a managed system. That means moving from “we have a backup circuit” to “we have predictable, provable store survivability.”
A managed failover approach typically includes:
- Application-aware validation. Testing and monitoring that confirms payment flows, POS connectivity, and key SaaS applications work during failover, not just that the circuit is reachable.
- Standardized edge design. Repeatable configurations across stores, so failover behavior is consistent and supportable at scale.
- Policy-based routing and SD-WAN orchestration. Intelligent path selection that balances performance, cost, and security requirements, especially under degraded conditions.
- Diverse connectivity options. A blend of terrestrial and non-terrestrial paths, including satellite and cellular, to reduce correlated failure risk.
- 24/7 operational ownership. A network operations center that sees issues early, manages incidents end to end, and coordinates with carriers and store teams.
- Proactive lifecycle management. Continuous tuning as traffic patterns and store technology evolve, so the backup strategy does not become outdated.
This is where a managed services provider model matters. SageNet’s heritage in hybrid satellite and terrestrial networking, combined with 24/7 U.S.-based NOC support, is built for multi-site organizations where downtime is immediately visible at the register and in the aisles.
Where enterprise Starlink fits, and why “managed” is the difference
Starlink has changed what is possible for reach and speed of deployment, especially where terrestrial services are constrained or slow to deliver. But for enterprise retail and grocery environments, the key question is not whether Starlink works. The question is how it is integrated, monitored, secured, and operationalized as part of a broader resilience architecture.
In a managed model, non-terrestrial connectivity can play several roles, depending on site profile and risk tolerance:
- Primary connectivity for hard-to-reach sites where fiber is not feasible or timelines are unacceptable.
- True diversity for business continuity so stores have an independent path when terrestrial infrastructure fails regionally.
- Rapid deployment connectivity for new locations, temporary pop-ups, remodels, or emergency restoration.
What turns that capability into resilience is managed execution: standardized designs, SD-WAN policy integration, security controls, and continuous monitoring from a 24/7 NOC.
A practical checklist: how to evaluate whether your backup strategy is real
- Can you prove payments work during failover? Not just link status, but real transaction flows.
- Have you tested failover during peak traffic? Off-hours tests do not replicate reality.
- Do you know your current bandwidth and performance needs? Store application stacks have changed dramatically.
- Is your backup truly diverse? Validate last-mile and upstream dependencies.
- Do you have consistent configurations across stores? Variability increases risk and slows recovery.
- Who owns outcomes during an incident? If the answer is “the store manager and a help desk ticket,” you do not have a continuity system.
Build store-level continuity that matches the reality of modern retail
Retail and grocery leaders need predictable stores. When something breaks, they want the peace of mind that their business can still run, transactions will clear, and the customer experience will continue to hold.
Backup connectivity that fails when it is needed is not resilience. It is a false sense of security. The path forward is a managed failover strategy that treats continuity as an operational discipline, not a circuit inventory.
Next step
If you are re-evaluating store survivability, SageNet can help you assess your current failover readiness and design a managed approach that integrates terrestrial connectivity, SD-WAN policy, and enterprise satellite options like Starlink into one operational model.